
Introduction: The Importance of Web Scraping Datasets for Data Collection
A web scraping dataset is useful only when you can explain what each record represents, when it was observed, and what the collection missed. A large export may still contain duplicate offers, missing prices or mixed snapshot dates. This guide shows how to define a dataset, collect a bounded sample, validate it and report conclusions that the records actually support. For a concrete file inventory and coverage example, explore the September 2024 Shopee shop dataset, which contains listing snapshots from 15 selected shops across three markets.
- Introduction: The Importance of Web Scraping Datasets for Data Collection
- What is a Web Scraping Dataset?
- Key Benefits of Using Web Scraping Datasets
- How to Collect Web Scraping Datasets
- Legal and Ethical Considerations in Web Scraping Datasets
- Conclusion: Unlock the Power of Web Scraping Datasets for Business Success
What is a Web Scraping Dataset?
A web scraping dataset is a collection of observations extracted from web pages, such as product offers, displayed prices or review text. Extraction does not automatically make those observations complete or analysis-ready. Define the unit of a row: for example, one seller’s offer for one variant in one market at one observation time. A product, listing, variant and seller are different entities.
Keep the raw export and a separate cleaned version. Record the source URL, observation time with timezone, market, collection scope and transformations. W3C’s Data on the Web Best Practices recommends documenting provenance and data quality so consumers can judge whether a dataset suits their purpose. This article’s worked example is fictional; it does not describe any Easy Data download.
Key Benefits of Using Web Scraping Datasets
-
Repeated observations
A scheduled collection can reveal changes between snapshots. Record when each page was observed and when the file was delivered; “daily” is a schedule, not a guarantee that every row is current. A price could change again after collection. -
Measurable collection cost
Automation can reduce repetitive copying, but setup, maintenance, failed requests, validation and review still take resources. Compare total cost per usable record or completed monitoring period, rather than request count alone. -
Evidence within a stated scope
A collection can support comparisons among the pages and offers sampled. Rankings, pagination limits, unavailable pages and category choices can skew that sample. More rows do not establish full market coverage, competitor revenue or market share. -
Reproducible analysis
Retained inputs and explicit cleaning rules let another analyst check a result. Compare like-for-like variants, currencies, quantities, delivery assumptions and observation windows. Report the number of usable records behind each metric, including what was excluded. -
Scoped business research
Business-directory observations may support research, but a public contact detail is not permission for unrestricted reuse or outreach. Minimize personal information and assess the proposed use before collection; see the privacy considerations below.
How to Collect Web Scraping Datasets
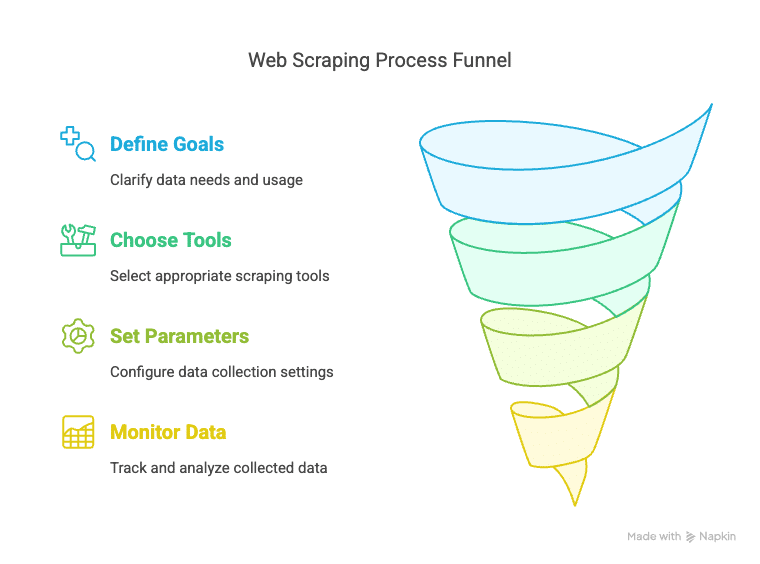
Start with the decision and the permitted collection scope, then choose a tool. The following steps take a dataset from its definition to a checked export. For the wider workflow, see our web scraping process guide.
1. Choose the Right Scraping Tool
Write a small acceptance brief first: which market, which entity, which fields, which snapshot window, and what counts as a usable row? Then test a tool on representative permitted pages, including missing-field and pagination cases. For a scheduled workflow, the scraping-agent selection guide covers monitoring, failure ownership and alert checks. Examples include:
- Scrapy: A Python crawling framework with feed exports including CSV, JSON and JSON Lines. Configure a fixed CSV field order; export success alone does not verify the records.
- Octoparse: A visual collection tool with templates and custom workflows, described in its getting-started guide. Test the workflow against your actual page types and required output.
- ParseHub: A visual tool with click and dynamic-loading controls. Pagination and loading behavior still need to be configured and checked for the target site.
- Beautiful Soup: A Python HTML/XML parser for extracting fields from a document you provide. Fetching pages, running JavaScript, scheduling and storing results require other components.
2. Define Your Data Collection Goals
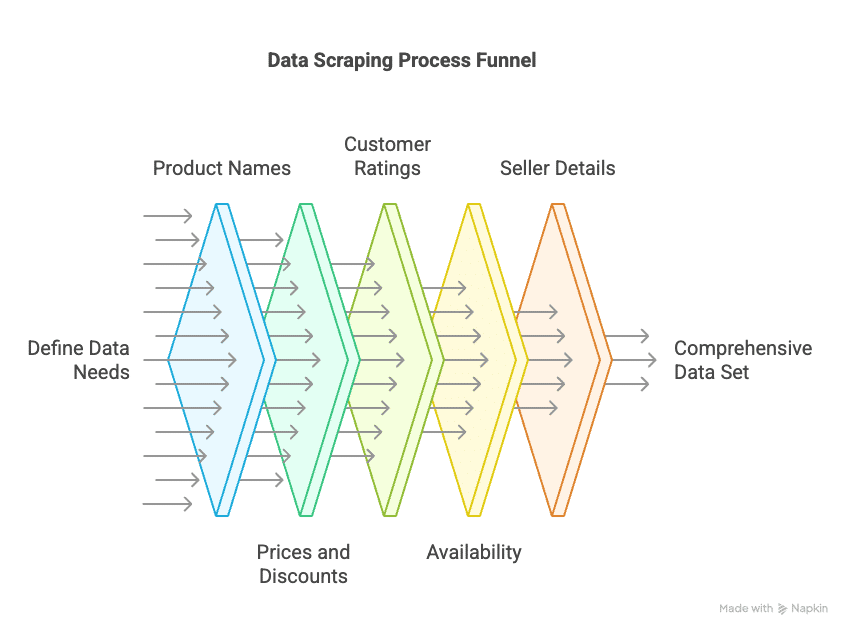
Turn the brief into a field dictionary before collecting at scale. For a product-offer dataset, define the following distinctions:
- Product and variant identifiers, seller identifier, market and source URL. A title is descriptive text, not a reliable unique key.
- Displayed rating and review count, with observation time. They do not establish buyer demographics or a representative sentiment sample.
- Price amount, currency, quantity or pack size, and whether shipping, vouchers and taxes are included, excluded or unknown.
- Availability label as observed. A missing price or failed fetch is unknown, not zero price, zero inventory or an out-of-stock conclusion.
Choose a uniqueness key that matches the analysis. For a single-snapshot offer table, include market, seller, listing, variant and observation time where those identifiers exist. If a key field is missing, flag the row for review instead of guessing. Keep later observations as history, not duplicates.
3. Set Up Scraping Parameters
Record the collection settings with the export so a later run can be compared on the same basis:
- Target scope: Save the seed URLs, category or query filters, market and page limits. A completed crawl of these targets is not a count of the entire marketplace.
- Observation window: Record start and end times, timezone and failed targets. Keep mixed-date files distinct or label the combined period; do not relabel them as one snapshot.
- Output contract: Specify field names, types, encoding, currency conventions and how missing values are represented. Use CSV for a defined flat table or a suitable structured format for nested values; verify that the exported file opens and parses as intended.
Set bounded request rates and retries appropriate to the permitted source, and stop or investigate access denials rather than treating them as successful empty pages. Preserve logs of attempts, failures and parser versions. The service evaluation guide explains why successful requests and usable delivery are different measures.
4. Run the Scraping Tool
Run a small pilot and inspect the records before expanding it. Check that later pages contain new expected items, that empty fields are explainable, and that a login or error page is not being parsed as product data. Track attempted targets, successful fetches, extracted rows and validated unique observations separately. A completed job can still produce an incomplete dataset.
5. Clean and Analyze the Data
Preserve the source file, then create a cleaned output with a change log. Remove only confirmed duplicate observations within the chosen key and time scope. Keep missing values explicit, retain rejected rows for diagnosis, and check types and units before calculating metrics. Do not combine currencies or compare different pack sizes as though their prices were equivalent.
Worked example: four target offers, not four usable prices. This fictional pilot targets four sellers’ offers for the same product variant, in Vietnam, within one specified observation window. All displayed amounts below exclude shipping; no real marketplace or Easy Data dataset is represented.
| Target or row | Observed outcome and treatment |
|---|---|
| Offer A | VND 100,000. Exported twice with the same key, timestamp and values. Keep one observation in the cleaned file. |
| Offer B | VND 120,000. One observation with a valid price. |
| Offer C | Page observed, price missing. Retain the observation and its missing-price flag; exclude it from price arithmetic. |
| Offer D | Fetch failed. No observation row; retain the failure in the target log. Do not label the offer unavailable. |
The raw export has 4 rows; removing one confirmed duplicate leaves 3 unique observations. Target coverage is 3 ÷ 4 = 75%. Price completeness among observed offers is 2 ÷ 3 ≈ 66.7%, while priced coverage of all targets is 2 ÷ 4 = 50%. These denominators answer different questions.
The median of the two known comparable prices is VND 110,000. It describes those two offers only, not a marketplace-wide typical price. Inserting a zero for Offer C would produce a false median of VND 100,000. A later dated observation of Offer A would belong to a new snapshot, not be removed merely because the offer identifier repeats.
Legal and Ethical Considerations in Web Scraping Datasets
Review the intended collection and reuse before running a scraper. Technical accessibility does not settle rights, contractual obligations or privacy requirements. These are issues to assess for the specific source and use:
- Source terms and rights: Review the applicable terms and data licence, and use an authorized API or export when appropriate. Check separately whether the planned storage, analysis and redistribution are permitted.
- Robots instructions and access controls: Respect robots.txt, but do not treat an allowed path as permission to collect or reuse its content. RFC 9309 distinguishes crawler instructions from access authorization; do not bypass authentication or other access controls.
- Personal information: Public visibility does not remove privacy obligations. A joint statement from privacy regulators explains that publicly accessible personal information remains protected in most jurisdictions. Limit collection to what the purpose requires and assess the applicable rules before reuse or outreach.
A technical collection checklist is not a legal clearance. Record the source, permitted purpose, retention and sharing decisions alongside the dataset; seek qualified advice when those permissions or obligations are uncertain.
Conclusion: Unlock the Power of Web Scraping Datasets for Business Success
A useful web scraping dataset combines observations with a clear scope, documented fields and visible quality limits. Validate a pilot, preserve the raw records, report missing targets and calculate metrics with explicit denominators. Repeated, comparable snapshots can support monitoring; neither row count nor automation alone guarantees current, complete or representative evidence.
For help scoping an e-commerce collection, review Easy Data’s services and agree on a sample, field definitions and acceptance criteria before a larger delivery.
Related guides and references
Leave a Reply