

Introduction: Why Web Scraping Skills Are Essential for Data Collection
Web scraping is an essential tool for businesses, researchers, and developers looking to collect large amounts of data from websites. The ability to extract valuable data from online sources can provide insights into market trends, consumer behavior, and competitor strategies. However, effective web scraping requires more than just basic knowledge of tools; mastering certain web scraping skills is key to success. In this article, we’ll explore the top skills every web scraper should have to ensure efficient and accurate data extraction.
What are Web Scraping Skills?
Web scraping skills refer to the technical knowledge and abilities needed to effectively collect, parse, and process data from websites. These skills include a range of competencies, such as programming knowledge, understanding of HTML and CSS, familiarity with scraping tools and frameworks, and the ability to handle challenges such as dynamic content and CAPTCHA. Whether you are a beginner or an experienced scraper, these skills are crucial to mastering the art of data extraction.
First identify the source you actually need. An existing authorized file export can be parsed locally; collecting a changing website requires a retrieval step as well. Check whether an available export or documented API covers the required fields and dates before building a page collector. Our comparison of data scraping and web scraping explains this distinction.
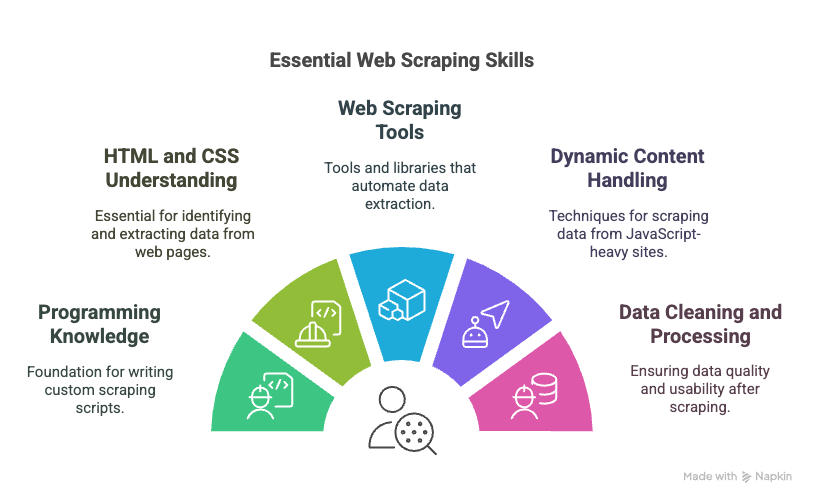
5 Essential Web Scraping Skills
-
Programming Knowledge
Python supports scraping workflows through libraries such as BeautifulSoup, Scrapy and Selenium. JavaScript, Ruby and PHP can also be used. Start by learning how to send a request, inspect its status and content type, parse a response, and save structured records. Add error handling and a small repeatable sample before increasing the collection scope.
Why it’s important: Programming allows you to write custom scripts that handle complex scraping tasks, such as navigating through multiple pages, handling pagination, and extracting data from dynamic websites.
-
Understanding HTML and CSS
A solid understanding of HTML (Hypertext Markup Language) and CSS (Cascading Style Sheets) is essential for web scraping. Websites are built using HTML and CSS to structure and style the content. By understanding how these elements work, you can easily identify the data you need to scrape from the HTML source code of a webpage.
Why it’s important: Knowing HTML and CSS allows you to pinpoint specific elements on a webpage (such as product names, prices, or descriptions) and extract them efficiently using scraping tools.
-
Knowledge of Web Scraping Tools and Libraries
Choose tools by their role. BeautifulSoup parses HTML or XML; it does not run a browser. Scrapy organizes crawling and extraction workflows. Selenium automates browser interactions. A documented API or an existing export may supply the required fields without page extraction. Confirm the data source before choosing the tool.
Why it’s important: Web scraping tools provide pre-built functions and methods that streamline the scraping process, helping you collect large volumes of data quickly and efficiently.
-
Handling Dynamic Content
If a value appears in the browser but not in the downloaded HTML, inspect where it comes from: embedded data, an additional response, or a browser interaction. Scrapy’s dynamic-content guide recommends identifying the data source first. Use a permitted structured response where available; use a browser when the required interaction or rendered content makes it necessary. Wait for a specific element or response rather than assuming a fixed delay proves the page is ready.
Why it’s important: Websites with dynamic content require specialized tools and techniques to extract data. Mastering how to interact with such sites will allow you to scrape data from a broader range of websites.
-
Data Cleaning and Processing
Define the output schema, data types, units and identity key before cleaning. Flag missing values and distinguish an unavailable field from a failed request. If a project needs imputation, document the rule and preserve the original value; do not silently fill gaps. Pandas documents missing-value detection and replacement. For repeated observations, decide whether the key includes a timestamp before removing apparent duplicates.
Why it’s important: Cleaning makes assumptions explicit, but it cannot establish that the source was accurate or the collection complete. Check required-field coverage and sample records against their source, and report missing pages separately from empty results.
Advanced Web Scraping Skills
Once you have mastered the basics, there are advanced web scraping skills you can learn to tackle more complex projects:
-
Handling Access Challenges
Recognize login, CAPTCHA and access-denied responses so they are not saved as successful data records. Record the failure and stop or defer that source according to the project’s access rules. Check whether an approved API, export or permission from the source owner can meet the requirement. A challenge response is not evidence that the product or record is absent. -
Request Limits and Reliability
Proxies and IP rotation do not guarantee access or remove a source’s restrictions. Set bounded concurrency, retry limits and backoff; keep a record of failed requests. Honor a server’s Retry-After instruction when supplied. Treat persistent blocking as a collection limitation to resolve, rather than repeatedly retrying until the job appears complete. -
Dealing with Pagination and Infinite Scroll
Follow the source’s next-page link, cursor or loading interaction and define a stop condition. Track visited pages and stable record identifiers to detect loops or overlaps. Keep failed pages in the job report. Reaching the last visible page does not prove complete coverage if earlier pages failed or listings changed during collection. -
Data Integration
For large-scale scraping projects, integrating scraped data into databases (such as MySQL or MongoDB) can help manage and store the data more efficiently. Knowing how to set up and use databases is an advanced skill that can significantly improve your scraping workflow.
Legal and Ethical Considerations in Web Scraping
As you develop your web scraping skills, it’s important to be aware of the legal and ethical implications of web scraping:
- Respect Website Terms of Service: Always check the terms of service for the websites you plan to scrape. Some websites prohibit scraping, and violating these terms can lead to legal action.
- Robots.txt: Follow the site’s crawler instructions. RFC 9309 specifies that the Robots Exclusion Protocol is not an access-authorization mechanism. An allowed path does not by itself establish permission to access or reuse the content.
- Data Privacy: Be mindful of data privacy laws such as GDPR when scraping personal data. Ensure that your scraping activities are compliant with legal standards.
Conclusion: Master Web Scraping Skills for Effective Data Collection
Mastering web scraping skills is essential for anyone looking to collect and analyze large volumes of data from websites. Whether you’re using web scraping for market research, lead generation, or competitive analysis, developing strong technical skills will help you scrape data efficiently and accurately. With the right knowledge of programming, web scraping tools, and dynamic content handling, you can unlock the full potential of web scraping and gain valuable insights to drive business success.
Practice exercise: For a permitted sample of product listings, define a record with the listing identifier, variant, displayed price, currency, observation time and source URL. Save the raw response alongside the parsed output. Test a missing price, a duplicate identifier, a failed request and a second page. Your report should show which records passed validation and which need review; this is a suggested exercise, not a claim about a completed dataset. If you need a managed collection workflow, use the Shopee data scraping service page to discuss the market, fields, collection frequency and delivery format.
External Links
Leave a Reply