
Web scraping vs web crawling is one of the most misunderstood comparisons in data extraction. While both involve automated interaction with websites, they serve very different purposes. In simple terms, web crawling discovers and maps web pages, while web scraping extracts specific data from them. Understanding this distinction is critical for building scalable web scraping for ecommerce data systems in 2026.
- Web crawling discovers URLs and maps website structures.
- Web scraping extracts specific data like prices, reviews, or product details.
- Crawling manages page retrieval and discovery.
- Scraping extracts selected fields from retrieved content.
- A workflow can combine both, or start from an existing list of product URLs.
When businesses compare web scraping vs web crawling, they often assume they’re interchangeable. They’re not. In real-world e-commerce environments, confusing the two can lead to poorly designed data systems, unstable pipelines, or unnecessary infrastructure costs.
What Is Web Crawling?
Start with the URLs you already have. Crawling is useful when you need to discover or revisit pages; a separate discovery crawl is unnecessary when a reliable product URL list or authorized feed already supplies your targets.
Web crawling is the automated retrieval of web pages, often combined with discovering further URLs. Indexing is a separate processing step, not an automatic result of crawling. A web crawler (sometimes called a bot or spider) moves from page to page by following hyperlinks, gradually mapping the structure of a website or even an entire digital ecosystem.
For marketplace monitoring, the crawler manages which pages to retrieve and revisit. The same program may also extract fields. Useful discovery questions include:
- What pages exist?
- How are they connected?
- What new pages have appeared?
In ecommerce environments, crawling often acts as the mapping layer of a marketplace.
For search engines, a fetched page is not necessarily indexed or shown in results. Google documents crawling, indexing and serving results as distinct stages. For extraction projects, Scrapy spiders demonstrate how one callback can produce both extracted items and requests for additional pages.
How Web Crawling Works
At a technical level, crawling follows a repeatable pattern. A system starts with a list of seed URLs. It sends requests, parses HTML to find links, adds new URLs to a queue, and continues expanding its coverage.
For example, on a large marketplace, a crawler might:
- Discover reachable category pages within the chosen scope
- Detect new product listings
Over time, repeated retrieval can build a map of the pages found within that scope. It is not proof of complete marketplace coverage: inaccessible pages and undiscovered links remain gaps. Authorized catalog feeds and existing URL inventories can also supply discovery data.
When Is Web Crawling Used?
Web crawling is useful when you need systematic discovery, page retrieval or repeat visits:
- Search engines rely on it to index the web.
- Ecommerce platforms use it to audit catalog size.
- Brands use it to detect new competitor entries.
If your question starts with:
- “How many…?”
- “Where are…?”
- “What new pages…?”
You are likely describing a crawling problem.
What Is Web Scraping?
Web scraping is the automated extraction of specific data points from webpages. Instead of mapping links, scraping isolates meaningful fields (such as product names, prices, ratings, stock levels, or seller metadata) and transforms them into structured datasets.
Scraping answers a different class of questions:
- What is the price today?
- How many reviews does this product have?
- Is this SKU in stock?
- Has the rating changed?
Crawling tells you where the page is. Scraping tells you what the page contains.
How Web Scraping Works
In practice, the process of web scraping is layered: identifying page structure, extracting fields, and structuring output.
But this is only the mechanical layer. The critical step (often underestimated in discussions about web scraping vs web crawling) is normalization. Raw scraped data may include currency symbols, inconsistent decimal formats, campaign-driven discounts, or region-based variations. Without cleaning and standardization, data cannot be reliably compared over time.
Finally, structured web scraping data feeds dashboards and analytics systems.
When Is Web Scraping Used?
Web scraping is one way to obtain structured information when the required fields are available on pages and a suitable authorized API or export is not available. Common applications include:
- Price monitoring across competitors
- Tracking rating fluctuations
- Recording displayed availability, with missing or failed observations marked separately
- Monitoring promotional campaign shifts
A scrape records an observation. Detecting change requires comparable observations from different times, matched to the same product, variant and market. Crawling results can also support analytics, such as measuring discovered URL coverage and retrieval failures.
Web Scraping vs Web Crawling: Key Differences
| Criteria | Web Crawling | Web Scraping |
|---|---|---|
| Purpose | Retrieve pages and discover URLs | Extract specific data fields |
| Output | URL lists, structural maps | Structured datasets |
| Scope | One site, a selected section or many sites | Selected fields across a small or large page set |
| Data Type | Page responses, links and retrieval metadata | Content-level information |
| Business Value | Visibility and coverage | Actionable intelligence |
The most important insight here is not that one is better than the other. It is that they operate on different layers of the data stack:
- Crawling schedules page retrieval and can expand a URL queue.
Scraping selects fields from retrieved content. - A crawler can revisit known pages as well as discover new ones.
An extractor can process those responses without a separate second download.
In modern ecommerce systems, treating web scraping vs web crawling as competing methods is a conceptual mistake. They are complementary layers.
How Crawling and Scraping Work Together in Real E-commerce Data Systems
In real-world ecommerce environments, web scraping vs web crawling is not an either-or decision. They form a pipeline.
Scenario 1: Marketplace Monitoring Pipeline
As an illustrative design exercise, consider a brand planning to track 20,000 SKUs across Southeast Asian marketplaces. This number describes the example, not a measured Easy Data deployment.
The proposed system checks selected category pages on a defined schedule to discover product URLs. Extractors then record available price, rating and displayed stock fields, along with the observation time. A page that is absent from one crawl is not automatically delisted: retrieval errors, pagination gaps and temporary unavailability need separate review. Normalize the observations before comparing them with earlier snapshots.
New listings can enter through discovery crawls, authorized feeds or maintained URL lists. Extraction supplies fields when the source is a web page; a suitable API or export may already provide them. Choose the combination that supplies the required coverage with observable failures.
Scenario 2: Competitive Intelligence Architecture
Crawling maps competitor storefront structures and detects catalog expansion. Scraping extracts pricing shifts, campaign banners, review growth, and stock volatility. Analytics engines then interpret those signals.
The competitive advantage does not come from collecting links or raw HTML. It comes from connecting structural awareness with content intelligence.
Scenario 3: Multi-Country Expansion Strategy
Southeast Asian marketplaces add layers of complexity, such as multiple currencies and localized campaigns. Crawling can map the selected pages in each market, while scraping records the fields shown there. A separate validation and normalization step must retain currency, variant, campaign conditions and observation time before prices can be compared.
This is why many companies either build internal data engineering teams or collaborate with specialized providers like Easy Data. Through structured ecommerce data scraping services, the focus shifts from simply collecting website data to maintaining resilient pipelines that deliver standardized, decision-ready datasets aligned with fast-moving Southeast Asian ecommerce environments.
Legal & Ethical Considerations in Southeast Asia
Any serious discussion of web scraping vs web crawling must include compliance.
- Public vs restricted data: Public availability does not automatically mean unrestricted usage. Some data may be accessible without login but still governed by platform policies.
- Marketplace terms of service frequently define acceptable automation behavior. Ignoring them can result in IP bans or legal complications.
- Rate limiting: Excessive request frequency can disrupt platforms and trigger automated defenses. Responsible scraping practices involve controlled request pacing, monitoring error rates, and avoiding interference with platform stability.
Ethical data collection is not just about avoiding penalties. It protects long-term operational continuity.
Which One Does Your Business Actually Need?
Choose the workflow from the decision you need to support, the available source and the URLs you already know. Company size alone does not determine whether you need discovery, extraction or both.
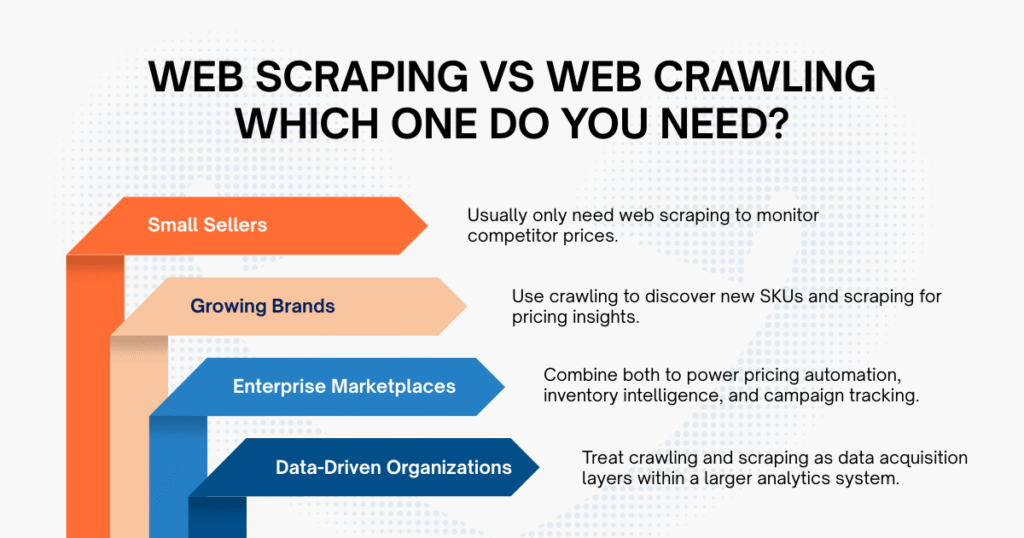
- Small Sellers: For a fixed competitor list, start with those product URLs or an authorized export. Add discovery only when finding new listings is part of the task.
- Growing Brands: Combine discovery and extraction when the monitored assortment changes. An existing feed may already cover the discovery requirement.
- Enterprise Marketplaces: Operate complex systems where crawling maps ecosystem shifts, and scraping powers pricing automation, inventory intelligence, and campaign monitoring.
- Data-Driven Organizations: These companies do not treat crawling and scraping as tools; they treat them as data acquisition layers within a broader analytics architecture.
At higher maturity levels, the real question is not web scraping vs web crawling, but how to design both for resilience and scale.
The Future of Web Scraping and Web Crawling in 2026 and Beyond
While the distinction remains, the technology around web crawling and web scraping is rapidly evolving.
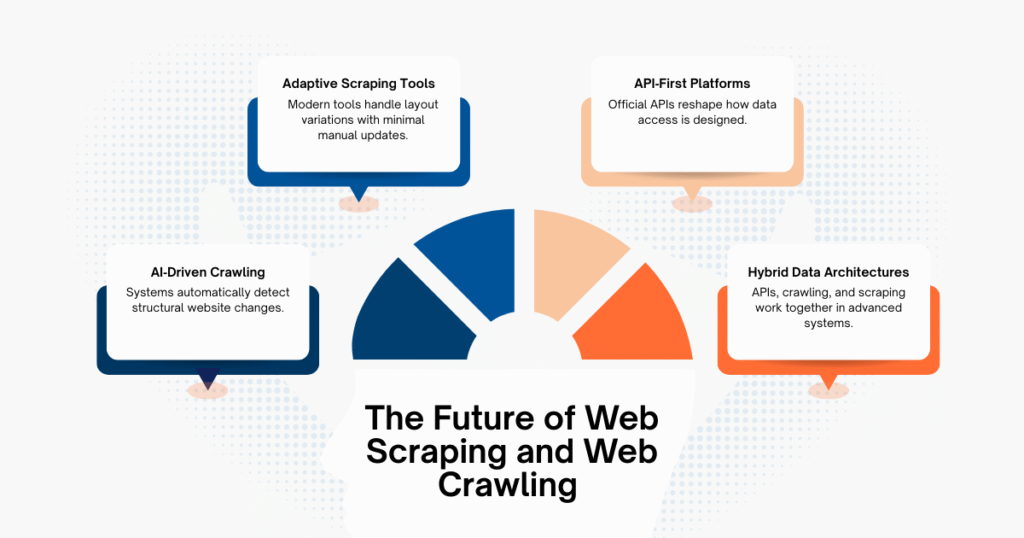
When evaluating AI-assisted web scraping tools, test their output against known examples and changed layouts. An extractor that still returns rows may silently select the wrong price or product. Treat schema checks, sample review and failure alerts as requirements rather than assuming automation removes maintenance.
Before building a hybrid workflow, check whether an authorized API or export covers the fields, markets and refresh schedule you need. Document any remaining coverage gaps before adding page discovery or extraction. In frameworks such as Scrapy, item pipelines provide a separate place for validation, duplicate handling and storage.
Freshness depends on the collection schedule, successful retrieval and processing delay. Report the observation time and known gaps with the dataset; do not describe scheduled snapshots as real-time data.
A practical brief before you build
For a Shopee price-monitoring project, write down these decisions before choosing tools:
- Coverage: name the market, seller or category scope and whether the product URL list is fixed or needs discovery.
- Observation: retain the product and seller identifiers where available, variant, displayed price, currency, source URL and collection time. Keep missing values distinct from zero.
- Validation: compare a reviewed sample with the source, count failed requests and missing required fields, and flag unexpected changes before sending data to a dashboard.
- Freshness: define a review interval suited to the business decision and show the last successful observation. A failed refresh must not look like a new price.
If the input may be a spreadsheet, file or API instead of a website, see our comparison of data scraping and web scraping. Use this brief when discussing scope with an internal developer or a data provider.
Conclusion
Understanding web scraping vs web crawling is not about choosing one over the other. It’s about recognizing their roles within a data pipeline.
- Crawling discovers structure.
- Scraping extracts intelligence.
- Together, they power scalable competitive systems.
In fast-moving e-commerce environments, especially across fragmented Southeast Asian marketplaces, designing the right balance between breadth and depth can determine whether your data becomes a strategic advantage or just another unstable script.
Leave a Reply